From Bellman Consistency toward Bellman Optimality: Constrained Online Critic Learning for Nonlinear Optimal Control
- Abstract
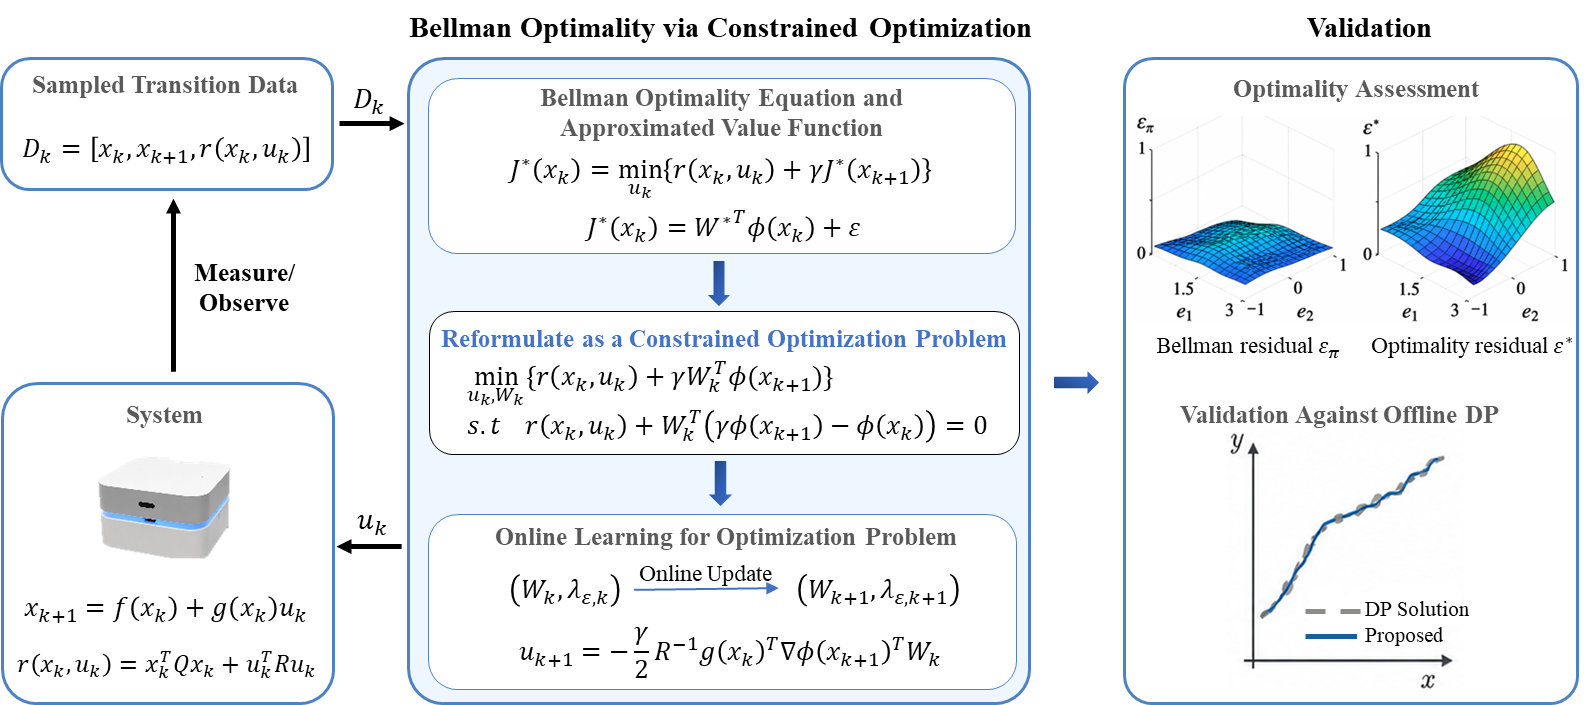
This paper proposes a constrained online critic-learning method for discrete-time control-affine nonlinear systems that moves beyond policy-dependent Bellman residual reduction toward Bellman optimality. Because a small policy-dependent residual does not verify minimization over alternative controls, the method formulates online critic learning as a constrained optimization problem, with the one-step Bellman backup as the objective and Bellman consistency as an equality constraint. The resulting Lagrangian-based law updates the critic weights and Bellman multiplier from sampled transitions and uses the critic’s state gradient for policy improvement. Lyapunov analysis establishes uniform ultimate boundedness of the learning errors. Real-world autonomous mobile robot experiments show that its trajectory root-mean-square error against an offline dynamic programming reference is 73.8% and 74.9% lower than those of one-step temporal-difference learning (TD(0)) and normalized adaptive dynamic programming, respectively. Complementary simulations show that its accumulated Bellman optimality residual over the evaluated state-error grid is 52.2% and 62.4% lower than those of the same methods, respectively. Additional learning reduces the residual along a newly encountered trajectory without substantially increasing it around the original trajectory.